

Failover
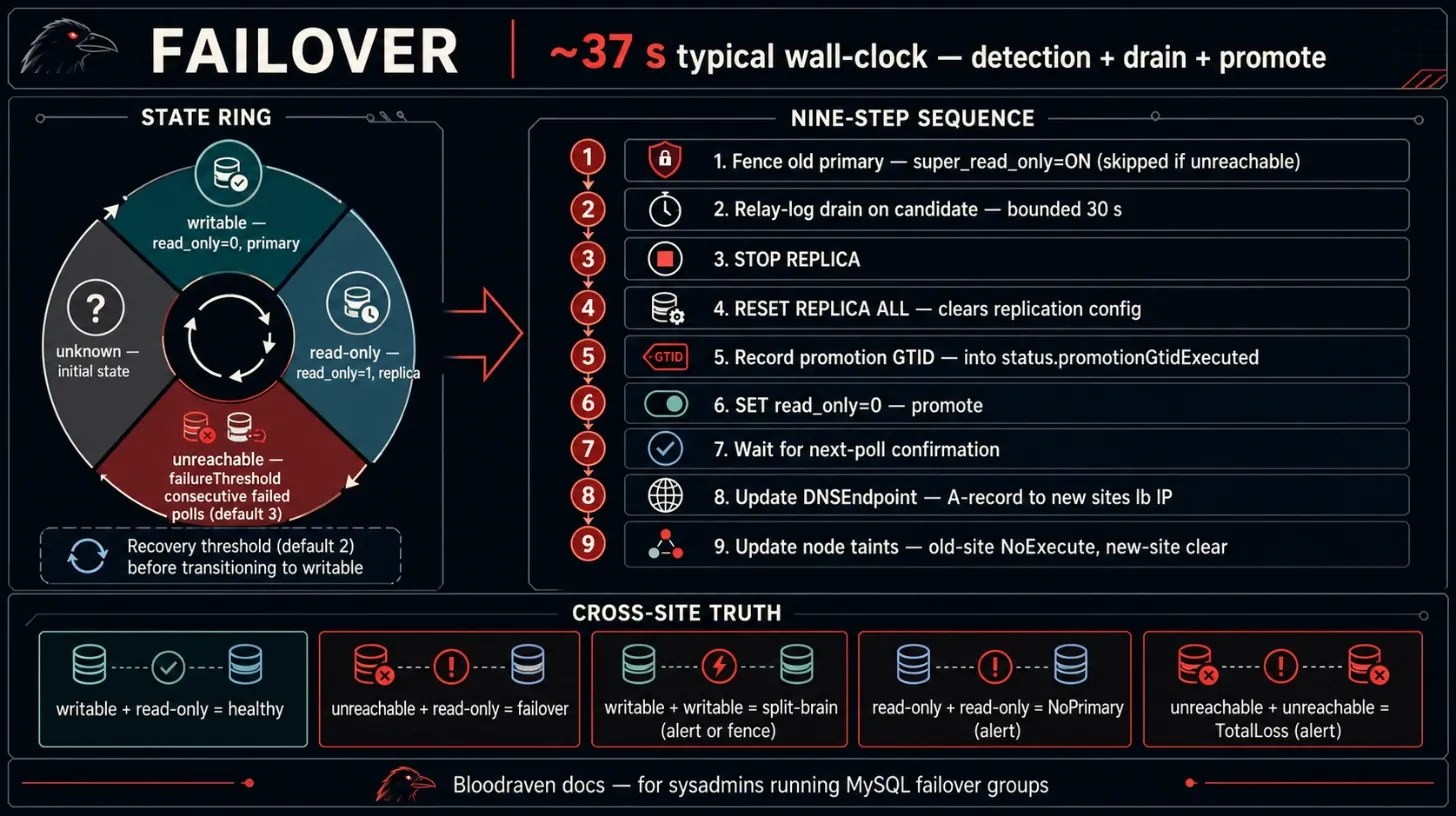
This page covers the state machine that drives MySQL failover decisions, the exact sequence of operations during a failover, Dragonfly follow-along behavior when enabled, the anti-flap cooldown, and ordered updates for zero-downtime rollouts. For the bounded-RPO contract and the exact set of transactions that can be lost on emergency failover, see Durability and RPO. For what happens when the operator itself is unavailable during a failure, see Operator availability.
State machine
Each site in a failover group is tracked independently. The possible states are:
| State | Meaning |
|---|---|
Unknown | Initial state after an operator start, until the site is classified. A read_only=1 answer classifies it at once; a read_only=0 answer needs recoveryThreshold polls |
Writable | MySQL is reachable and read_only=0 |
ReadOnly | MySQL is reachable and read_only=1 |
Unreachable | MySQL has failed the configured number of consecutive polls |
State transitions
Debouncing:
- A site transitions to
Unreachableonly after failureThreshold consecutive failed polls (default: 3). For the first fault in an otherwise healthy group, the default 2-second base interval means about 6 seconds of downtime before the operator considers the site unreachable. - A site transitions to
Writableonly after recoveryThreshold consecutive successful polls showingread_only=0(default: 2). This prevents premature promotion on transient successes. - Transitions to
ReadOnlyare immediate (single poll) since this is a safe, non-destructive state.
spec.pollInterval is the poll loop's cadence, and every site that is
reachable is probed on every poll. A site that has reached failureThreshold
and keeps failing is probed less often: with the defaults its probes back off
from 2 seconds to 4, 8, 16, and then a 30-second cap. The backoff is per site.
A site that stays down does not slow the probes of any other site, so the
primary's loss is still detected in about 6 seconds while a reader or DR site
is down. A successful probe resets that site's failure count and returns it to
the base interval.
The backoff does delay noticing that a long-down site has come back: its next probe can be up to 30 seconds away. The sidecar's self-fencing rules cover a returning old primary during that window.
Cross-site evaluation
After updating individual site states, the operator evaluates the pair together:
| Site A | Site B | Action |
|---|---|---|
Writable | ReadOnly | Healthy -- no action needed |
Unreachable | ReadOnly | Promote Site B -- the Degraded condition reason is SiteUnhealthy until topology converges |
ReadOnly | Unreachable | Promote Site A -- the Degraded condition reason is SiteUnhealthy until topology converges |
Writable | Writable | Split brain -- see Split-brain resolution |
ReadOnly | ReadOnly | No primary -- alert, no automatic action (with one exception, below) |
Unreachable | Unreachable | Total loss -- alert, no automatic action |
Unknown | ReadOnly | Initializing -- right after an operator start; no alert, no automatic action (see Initializing after an operator start) |
The operator only takes automatic action for the failover case (and, opt-in, for split brain). All other anomalous states require human investigation.
Failover is not a Degraded condition reason. Alert on
Degraded=True, reason=SiteUnhealthy for this topology state, on the
FailoverExecuted Kubernetes Event for a completed promotion, or on an
increase in bloodraven_failovers_total. A condition alert that matches
reason=Failover never fires because the operator does not emit that value.
The table is the two-candidate core reduced to two columns. In an N-site
group, only PrimaryCandidate sites can be the active site, promotion target,
or split-brain winner. DisasterRecovery and ReadOnly sites are non-promotable. A
writable non-promotable site is an anomaly and is fenced on every poll; a
reader is fenced even when it is the sole writable site. Reader outages and
replication failures remain visible per site but are excluded from group
readiness and degradation calculations. Readers never trigger node taint
changes or become active DNS targets.
Exception — re-asserting a fenced promoted primary. A freshly promoted primary can be fenced back to read-only by its own sidecar: the sidecar's fencing lease may still be stale when the promotion lands (for example, the operator restarted after a full-site outage and promoted before its auxiliary Service endpoint became Ready, so the sidecar's operator probes kept failing while the operator was already driving MySQL). That leaves every site reachable and read-only — a state the table above refuses to touch, because without history it is indistinguishable from a fresh-start condition that needs human input.
The operator, however, does have history: status.lastFailover.target names the site it made authoritative. When all of the following hold, the operator restores writability on that site instead of alerting and waiting:
- a prior failover is recorded and its target is reachable, read-only, and a
PrimaryCandidate; - every other site is also reachable and read-only, both in the operator's debounced state and on a live
@@read_onlyread just before the re-assert (an unreachable site hands the decision back to the normal failover row above); - the target contains every other site's
GTID_EXECUTEDand the recordedstatus.lastFailover.promotionGtidExecuted— restoring it cannot lose transactions or create a second primary.
A group that has never failed over gets the same protection for the last site the operator saw as its unique writable primary (status.activeSite survives an operator restart, unless it was already empty), with one limit. A site the operator only observed as primary is lifted only from the read_only=ON every mysqld boots with (super_read_only OFF), never from a fence: a self-fenced primary with no failover history still waits for a human. Every mysqld starts with read_only=ON, so a primary whose MySQL container restarts comes back read-only and is re-asserted on the next poll. A site the operator made primary itself is re-asserted from any fence, as a failover target is: the fresh-deploy bootstrap reports its seed as the active site the moment it makes the seed writable, so a seed fenced by its own sidecar's startup safety net is re-asserted the same way. The log line's authority field says which applied: lastFailoverTarget or lastActiveSite.
The re-assert is rate-limited to once per failoverCooldown, logs re-asserting fenced promoted primary (see the log schema), and increments bloodraven_primary_reassert_total. GTID divergence between the sites still blocks it — that genuinely needs a human. The one exception is a peer that already carries a divergence report (Divergent replicas): its recorded divergentGtid is not held against the target, because those transactions are already reported, stay on the peer, and are re-audited against the re-asserted primary. Without it, an emergency failover that deliberately promoted a clean candidate over that peer could never re-assert the candidate after a fence-back. Anything the peer holds beyond its recorded set still blocks the re-assert.
Initializing after an operator start
A new topology manager (after an operator restart, a leader change, a new group, or a change to the group's topology settings) starts every site in Unknown. A read-only answer classifies a site on the first poll, but the primary's writable answer needs recoveryThreshold polls. Until every PrimaryCandidate has been classified, a topology with no confirmed writable site is reported as Initializing rather than NoPrimary, because NoPrimary claims every candidate was seen read-only:
ReadyandDegradedareUnknownwith reasonInitializing, and the message names each unclassified site and whether it has answered writable. NoALERTlog line and noNoPrimaryDetectedor other topology Event is emitted, and the first real verdict does not emitSiteRecovered. The deployment API reportsstable=falsewithunstableReason: Initializing.- With the defaults this lasts one poll (about 2 seconds) for a healthy group. A site whose probes are failing stays
Unknownfor up tofailureThresholdpolls before it becomesUnreachable. Initializingis bounded. A site that is stillUnknownafterfailureThreshold+recoveryThresholdprobes (5 with the defaults) is alternating between answers and errors, which the debounce never classifies. It stops counting towardInitializing: the group reportsNoPrimarywith an alert naming the site, and the operator logs WARNsite not classified after its probe budget; probes alternate between answers and errors. If that site had answered writable, it still holds back promotion of any other site.- The debounce still gates every action. A site that answered writable but is not confirmed is not the active site, DNS is not steered at it, and it is not fenced. No other site is promoted while it awaits confirmation, so a peer that becomes
Unreachablein that window cannot produce a second primary; the failover decision is made again when the site is classified. A primary that answers writable once and then dies is promoted over on the same poll as before,failureThresholdfailures after its last answer. - A writable answer is never hidden. If a second site answers writable, the group reports
SplitBrainat once, with a message naming the sites not yet confirmed, andSplitBrainDetectedfires. Fencing andsitePrioritiesresolution still wait until the second site is confirmed writable. - A group that is genuinely all read-only is still
NoPrimaryfrom its first poll. A site confirmedUnreachablewith a read-only candidate to promote still fails over while some other site has not answered yet; only a writable answer holds the promotion back.
Failover sequence
Choosing the candidate. Among the reachable PrimaryCandidate sites the
operator reads every candidate's GTID_EXECUTED and promotes the most
caught-up one; priority order breaks ties. A candidate that is empty in a
group that holds data, or that lacks status.lastFailover.promotionGtidExecuted, is
refused. A candidate carrying a divergence report (see
Divergent replicas) ranks below every candidate without
one, even when it has the fresher set: the freshest clean candidate wins
(logged failover picker: skipping divergent candidate). Preferring it can
leave transactions that only the divergent site holds, legitimate ones
included, off the new primary; the divergent site keeps its report, so they
are not silently dropped. Divergence never blocks an emergency failover: when
only divergent candidates remain, the freshest of them is promoted with an
ERROR failover picker: promoting a divergent candidate; no other candidate remains,
and once it is the confirmed primary the operator records the
DivergentPromotion status condition and a DivergentSitePromoted Warning
Event naming the set that became authoritative. The condition stays until an
administrator removes it. A further divergent promotion before that is added
to the same condition, newest last; it keeps the five newest records and says
when older ones were dropped (the Events and the operator log keep all of
them).
When the operator decides to fail over to a candidate site, it executes these steps in order:
- Best-effort fence the old primary with
SET GLOBAL super_read_only=ON. If no old-primary connection is available, the sequence continues because the failed site is already isolated from the operator. - Best-effort evict application connections from the old primary so clients reconnect through the primary Service or DNS. A failure is logged and does not block promotion.
- Drain relay logs on the candidate, bounded by 30 seconds. The drain is
complete once
Executed_Gtid_Setcontains theRetrieved_Gtid_Setthe candidate had when the drain began, so it returns as soon as the backlog already received is applied and does not wait on a receiver that is still fetching. A stopped SQL thread with pending relay log is restarted once. An IO-thread error, such as the connect error a candidate reports once its primary is dead, does not end the drain; only an applier (SQL thread) error does. A timeout or drain error is logged and promotion continues; the drain narrows the normal asynchronous-replication RPO but is not a zero-RPO gate. - Stop replication on the candidate with
STOP REPLICA. Failure stops the promotion attempt. - Remove the candidate's replication configuration with
RESET REPLICA ALL. Failure stops the promotion attempt. - Capture the promotion GTID with
SELECT @@global.gtid_executedbefore the candidate accepts writes. A read failure is logged and leaves the recorded value empty; it does not stop promotion. - Clear
super_read_onlyon the candidate. This is required because a sidecar or earlier fence may have set it. Failure stops the promotion. - Clear
read_onlyon the candidate, making it writable. Failure stops the promotion. - Confirm writability immediately with a bounded
read_onlyprobe. This is part of the same promotion attempt, not the next topology poll. If the probe fails, DNS and failover bookkeeping are not advanced, although the preceding write may already have made MySQL writable. - Record and publish the promotion. The operator records anti-flap and
promotion-GTID state and increments
bloodraven_failovers_totalbefore it best-effort updates theDNSEndpoint. A DNS write failure does not undo a successful MySQL promotion; poll-driven DNS reconciliation keeps retrying. Dragonfly follow-along, when enabled, starts after this MySQL path.
Node taints, the -primary Service selector, and follower source convergence
are poll-driven consequences rather than steps inside
FailoverController.Execute. The old site's transition to Unreachable
applies its taint before promotion. Later successful polls debounce the new
primary to Writable and remove its taint; the status update then lets the
resource reconciler move pod role labels and Service endpoints. Direct-source
convergence separately verifies and repairs each remaining follower after
replica status collection.
Direct-source convergence
Source convergence runs after replica status collection and outside the
promotion sequence. It is therefore able to repair a healthy wrong source
after an operator restart even when no failover history exists. Mutation is
allowed only when there is exactly one writable PrimaryCandidate, no second
writable site, and no bootstrap, update, restore, topology freeze, pending
promotion, planned failover, or split brain in flight.
For a wrong non-empty source, Bloodraven:
- Verifies that the active primary's
GTID_EXECUTEDcontains the follower's executed set. - Runs
STOP REPLICAand repeats both GTID reads and the containment check, closing the race where the SQL applier advances after the first check. - Runs
CHANGE REPLICATION SOURCE TOwith the configured credentials and TLS settings, withoutRESET REPLICA ALL. - Runs
START REPLICAand boundedly verifies the direct canonical hostname and both replication threads.
If containment fails, status becomes Blocked/GTIDDiverged and no unsafe
repoint occurs. A post-STOP containment failure leaves replication stopped.
Other bounded failures remain Pending/MutationFailed for a later safe retry.
This generic state is recorded in sourceHost, sourceConvergenceState, and
sourceConvergenceReason; it does not replace the
recoveryState/divergentGtid reporting of divergent replicas
and old primaries.
Divergent replicas
Healthy replication threads say nothing about whether a replica holds
transactions the primary never had. A replica keeps applying the primary's new
transactions while it carries extra history of its own, until a conflicting row
breaks it. Issue #202 is the example: an ordered update on v1.5.0 promoted a
standby before it received the old primary's last 221 transactions, and the
demoted site then replicated normally with those 221 transactions as errant
GTIDs while the group reported Ready=True and Degraded=False.
The operator audits every read-only follower with a replication channel,
promotable or not, against the confirmed primary: about every 30 seconds per
site, and immediately on the first poll after the operator starts, the
primary changes, a promotion or handoff completes, a fenced primary is
re-asserted, or a follower's receiver reports a new Source_UUID for the
active host (the primary was replaced under the same name). A maintenance
handoff refused because its candidate holds extra transactions makes that
candidate due on the next poll. A failed ordered-update attempt forces
nothing, so a rollout that keeps failing cannot make the audit run every
poll. It reads the follower's @@server_uuid and GTID_EXECUTED
first and the primary's second, then computes follower minus primary. A
follower's set only grows with transactions that are on the primary first, so
reading in that order never reports a transaction the follower applied between
the two reads. A result is discarded if the primary changed, a promotion or
update began, or either server's server_uuid changed while the audit was
reading. A failed or unparseable read changes nothing. The pass runs after the
poll's failure handling. A poll with no follower due probes nothing; when one
is due, confirming the primary and every read share one 5-second budget, so
the audit cannot delay the next poll's failure detection by more than that.
The audit is
skipped while a bootstrap, in-place restore, initial restore, planned
failover, ordered update or pending promotion is in flight.
A non-empty result makes the site divergent:
status.sites[].recoveryStateisRecoveryBlocked,divergentGtidanddivergentTransactionCountdescribe the extra set,divergenceDetectedByisReplicaAudit, anddivergenceComparedTonames the primary it was compared against. Old-primary recovery records the same fields withdivergenceDetectedBy=OldPrimaryRecovery.DegradedisTruewith reasonDivergentTransactionsand a message naming the site, the count and the set. This outranks the lag, thread and source-mismatch reasons; split brain, no primary and total loss still win.Readyis not changed, and the deployment API keeps granting leases: the group is serving, and an integrity warning on a replica must not stop application deployments. (A returning old primary's block still makes the deployment API report the group unstable, as before.)bloodraven_divergent_transactions{site}is set, the WARNdivergence detectedis logged withdetectedBy=ReplicaAudit, and aDivergentReplicaDetectedWarning Event is emitted on new or changed evidence.- Ordered updates and planned failovers will not promote the site (see Upgrade policy and Planned failover). Emergency failover still can, as a last resort.
The block is sticky. Healthy threads, a converged source and an operator
restart do not clear it; a restarted operator restores it from status. Only a
fresh audit proving the follower holds nothing the primary lacks clears it,
logged as divergence cleared: replica holds no transactions the primary lacks
with a DivergenceResolved Event. If the divergent site itself becomes the
primary, the block is not compared with itself: it becomes the
DivergentPromotion condition described under
Failover sequence.
No local transaction is exempt: a CREATE USER run on a replica is reported
like an order that never reached the primary, because a GTID set cannot tell
them apart. There are three ways to resolve a divergent replica, and each ends
with the audit clearing the block on its own:
- Discard the transactions. Save the errant binlog events first (decode
them with
mysqlbinlog --include-gtids='<divergentGtid>'on the replica), then reclone the site from the primary:kubectl bloodraven reclone <group> <site>, which builds the value the reclone interlock requires (or annotatebloodraven.shipstream.io/reclone-site=<site>:confirm=<group>:uid=<group uid>:gtidPrefix=<first 8+ characters of the divergentGtid's source UUID>). Before a block is recorded, a cold reclone usesreclone-site=<site>:confirm=<group>:uid=<group uid>. - Keep the transactions. Replay the decoded transactions on the primary (review them for conflicts first). The primary then holds their GTIDs and their rows.
- Accept the replica's divergence. When the transactions carry nothing
the primary needs, commit an empty transaction on the primary for each GTID:
SET GTID_NEXT='<uuid>:<n>'; BEGIN; COMMIT;and finallySET GTID_NEXT='AUTOMATIC';. This makes the GTID sets agree without moving any rows: the replica keeps rows the primary lacks. Once the audit clears, the replica is promotable again, and a later promotion makes its rows authoritative with noDivergentPromotionrecord. Use it only for transactions whose effects are absent from both sites, harmless, or already reconciled.
For maintenance on a replica that must not reach the primary's history, run it
with SET SESSION sql_log_bin=0 so it gets no GTID. There is no setting that
ignores divergence. Playbook 33 in the bloodraven-doctor skill walks through
the triage.
Dragonfly during failover
When spec.dragonfly.enabled=true, Dragonfly follows the MySQL failover group but remains best-effort cache/session state, not durable data.
During planned failover, Bloodraven inserts two Dragonfly phases before MySQL promotion:
WaitingForDragonflySynccaptures the source Dragonfly replication offset and waits for the target Dragonfly replica to catch up, bounded byspec.dragonfly.plannedFailover.maxSyncWait(default30s).PromotingDragonflyremoves the source pod'sbloodraven.shipstream.io/dragonfly-trafficlabel, promotes the target withREPLTAKEOVER, stamps the target asbloodraven.shipstream.io/dragonfly-role=master, and best-effort kills old-master clients so they reconnect through the active Dragonfly Service.
If sync or REPLTAKEOVER fails, spec.dragonfly.plannedFailover.onSyncTimeout controls the outcome. The default Proceed continues MySQL promotion and records status.plannedFailover.dragonfly.sessions: Lost (with dragonfly.reason DragonflySyncTimeout or DragonflyPromotionFailed). Fail rolls back before MySQL promotion and leaves the original MySQL primary active. A takeover that succeeded before the MySQL run failed leaves Dragonfly leading on the target; the run's result then carries the warning DragonflySessionsLost.
The run finishes a takeover (relabels the target master, demotes, evicts and recreates the source) only when this operator process sent REPLTAKEOVER for the run and received its success reply. Anything else is an unconfirmed takeover: a target that already reports role:master before REPLTAKEOVER is sent (a Dragonfly pod restarts with no --replicaof and empty data, so a target that restarted during the run is an empty standalone master), a lost reply (a timeout or transport error, not a server -ERR), and every re-run by another operator process (after a restart or a leader change) of a takeover whose intent is already recorded, which sends no REPLTAKEOVER at all. An unconfirmed takeover changes no Dragonfly role: the source is not demoted, its clients are not killed, its pod is not deleted, and the target is not relabelled; only the source's traffic label is put back so the active Service keeps its endpoint. The takeover is recorded Failed with dragonfly.reason: DragonflyPromotionFailed, a dragonfly.message that says it is unconfirmed, and a DragonflyPromotionFailed Event, and onSyncTimeout applies exactly as for a failed takeover: Fail rolls MySQL back (nothing was sent to the MySQL target), Proceed promotes MySQL and records sessions: Lost. Whatever the target did, the Dragonfly manager reconciles Dragonfly with MySQL through its normal drift and follow-up path once the run releases Dragonfly. If the Dragonfly master is neither the run's source nor its target (a Dragonfly-only promotion moved it), the takeover is refused as failed and nothing is stripped or sent. The takeover's result is recorded in its own write while the phase still reads PromotingDragonfly, so takeover.state: Succeeded (or Failed) can be seen briefly before the Promoting intent.
After a succeeded takeover the target stays the Dragonfly master (labels, status.dragonfly.activeSite, replica wiring) while the run's block reads PromotingDragonfly, Promoting, Publishing or RollingBack, also after a terminal marker ended the run, until a Dragonfly promotion to another site is stamped at or after the takeover's completion or the target is observed as a replica. A replica StatefulSet rollout does not restart the run's Dragonfly target while the run owns Dragonfly (dragonfly rollout: site is the planned failover's Dragonfly target; holding its restart).
Ownership of Dragonfly follows the planned-failover claim slot. With the group's topology manager registered, the slot decides: a run, its provisional grant, or an automation hold owns Dragonfly, and a run that released its claim after recording its promotion owns nothing, whatever its phase reads. Before the manager is registered (right after an operator restart) the status form decides: a run that still needs the claim, or a durable hold (status.plannedFailoverHold or a ManualRecoveryRequired terminal marker).
A Dragonfly snapshot upgrade pauses only the Dragonfly manager, never MySQL topology: an emergency MySQL failover during an upgrade supersedes it. The next upgrade reconcile ends the upgrade Failed with reason ActiveSiteChanged and hands the Dragonfly promotion for the new MySQL active site to the Dragonfly manager. A planned failover waits in admission (DragonflyUpgradeInFlight) while an upgrade is in flight. A snapshot-restore upgrade that spec.dragonfly.image drift asks for (upgradeStrategy: SnapshotRestore) does not start while a planned failover or hold owns Dragonfly, or while the effective Dragonfly master differs from status.activeSite: it waits, without moving any site and without holding up the rest of the reconcile (the planned failover it waits for keeps running), a Normal DragonflyUpgradeDeferred Event names the cause when it changes, and the run is retried every 10 seconds until the cause clears. An abandoned run is not restarted while spec.dragonfly is unchanged; see Snapshot-restore upgrade for the retry.
During emergency failover, MySQL promotion is the priority. After MySQL promotion succeeds, the MySQL poll loop only queues a Dragonfly promotion for the new MySQL active site and carries on; it never waits for the cache. The group's Dragonfly manager runs the promotion on its own goroutine between its polls, so a poll's observation, its status publication and a promotion never overlap. Only the latest queued request is kept; a newer MySQL decision replaces it even while it waits to run. When it runs it is checked against the group as it is then: it is dropped if a planned failover or snapshot upgrade owns Dragonfly, if a decision recorded after it (a planned failover claimed at or after the request's second, a MySQL failover to another site, or a Dragonfly promotion to another site while MySQL does not name the request's target) points elsewhere, or if its target has already been promoted. If the old Dragonfly master answers a 1s dial and PING, the operator tries REPLTAKEOVER with a 2s budget to preserve sessions. A takeover is coordinated by the master and cannot complete without it, so an unreachable old master skips straight to the fallback. If the takeover fails or is skipped, the operator falls back to REPLICAOF NO ONE on a fresh connection with its own budget: 14s after a failed takeover, because Dragonfly keeps the replica's REPLICAOF lock for the takeover budget plus 10s. That restores a writable Dragonfly master but does not guarantee session continuity. That fallback emits the Warning Event DragonflySessionsLost (not DragonflyPromotionSucceeded) and increments bloodraven_dragonfly_promotions_total{result="sessions_lost"}. If the fallback cannot be sent after a takeover, or its reply is lost, the outcome is unknown: a takeover can complete on the server after the client gives up. The operator then waits until the server can no longer be acting on the commands (the takeover budget plus 10s, plus 1s) and reads the target's role. A master is recorded as a completed promotion, with the same sessions-lost Event; anything else is a failed promotion, and the old source's traffic label is restored so the active Dragonfly Service is not left empty. Label updates, the role observation and the status.dragonfly stamp each get their own 5s budget, so a slow step cannot drop the status update. Every writer of a group's Dragonfly routing (the Dragonfly manager's polls and promotions, the planned failover's Dragonfly phase, the rollout promotion, the replica StatefulSet rollout, each snapshot-upgrade step and the reconciler's label sweep) holds one per-group gate and, after taking it, reads the group uncached from the API server, not from the informer cache, which can lag the previous holder's writes. The manager steps aside for a waiting planned failover or rollout only before it has sent a role-changing command; once REPLTAKEOVER or REPLICAOF NO ONE is on the wire, the promotion finishes and records its outcome first, even if the manager is being stopped. The gate outlives the manager: when a configuration or credential change restarts a group's managers, the replacement, and any planned failover in the meantime, waits for the old manager's last step. A planned failover that reaches its Dragonfly phase while an emergency promotion has already sent its command therefore waits for it with the MySQL source fenced: about 12-13s in practice (the takeover wait, then the fallback queued behind Dragonfly's lock), about 40s in the worst case with every step at its timeout. It reports the wait in status.plannedFailover.dragonfly.message and a Warning Event DragonflyPromotionDeferred. The promotion never returns an error to the MySQL path. If Dragonfly is unreachable, MySQL recovery still completes. A rollout promotion of a sync-proven target keeps the maxSyncWait/2 takeover budget.
The Dragonfly manager also handles Dragonfly-only failures. If the active Dragonfly master dies while MySQL remains healthy, the manager can promote the single healthy Dragonfly replica and leave status.activeSite for MySQL unchanged.
Old primary recovery
After an emergency failover, the old primary may come back online. The operator automatically detects this and takes action based on whether the old primary's data has diverged from the new primary.
Detection
On each poll cycle, if a site is read-only with no active replication (the signature of a former primary) while another site is the directly confirmed writable primary, the operator initiates recovery. Recovery is deliberately not gated on a recorded failover: a primary can change hands without one (a replica respawns writable and is adopted while the old primary respawns fenced, or the failover record was lost to a status-write outage plus an operator restart), and the orphaned ex-primary still needs to rejoin.
Only a genuinely fresh datadir is skipped and left to bootstrap/auto-clone. Freshness is decided from GTID history, not from the absence of user schemas: a site whose GTID_EXECUTED server UUIDs share nothing with the new primary (server-init transactions under a brand-new server_uuid) may still be treated as empty when it also has no user schemas. GTID tags are ignored for this check, because a tag does not change which server wrote a transaction: uuid:app:1-3 shares history with uuid:1-10. The divergence comparison that follows stays tag-exact. A returning cluster member always carries the cluster's shared UUIDs, so a schemaless but previously participating site still runs the divergence comparison — never a silent clone-over. If the new primary cannot be probed for this check, the operator fails safe toward recovery rather than toward the fresh-datadir path. The sequence:
- Fence the returning site with
SET GLOBAL super_read_only=ON(defensive — the sidecar may have already fenced it) - Drain application sessions until a pass finds none or
spec.connectionDrainTimeoutelapses (default30s). Each topology poll performs at most one bounded eviction pass, so recovery waits without blocking failure detection or failover progress. This runs after promotion, so it cannot kill the operator's promotion session. A timeout does not block recovery because the fence prevents writes; any survivor is limited to stale reads. - Query
@@global.gtid_executedon both the old and new primary - Compare GTID sets to determine if the old primary has any transactions not on the new primary
If the old primary returns writable (e.g., power was cut before the sidecar could self-fence), the operator first detects this as a split-brain condition and fences it immediately. The fence is retried on every poll cycle while the split-brain persists — a transient error on the first attempt (a network blip during the site's recovery turbulence) does not leave the returning site writable. Recovery proceeds once the site transitions to read-only.
No divergence (automatic rejoin)
If the new primary's GTID set contains all transactions from the old primary, there is no data loss. The operator automatically reconfigures the old primary as a replica:
SET GLOBAL super_read_only=ONSTOP REPLICARESET REPLICA ALLCHANGE REPLICATION SOURCE TO ... SOURCE_AUTO_POSITION=1START REPLICA
While the sequence runs, status.sites[].recoveryState is RecoveryInProgress and the RecoveryPending condition is True with reason RecoveryInProgress. The operator keeps that state until MySQL reports healthy replication and the bounded application-connection drain has completed, then writes replication Healthy (or Lagging) and gtidExecuted for the read-only site and clears recovery state.
Recovery and its connection drain stand down while another operation owns the sites: a planned failover that holds its claim (from Fencing until its Publishing or terminal record is durable), a planned-failover automation hold, an ordered update, or a promotion that no poll has yet observed as writable. Both kill sessions and rewrite replication, and the sites they would touch are the ones the handoff is using. A RecoveryInProgress site therefore stays that way for the length of the handoff (and for as long as a hold stands), and the drain starts over with a fresh spec.connectionDrainTimeout budget when it ends. Replication-source convergence stands down for the same window, and a topology manager restarted while its predecessor's ordered update is still finishing (a configuration or credential change) leaves the sites to that update until it exits. A planned-failover request that is only waiting for its claim (Admitting without a grant, or Deferred) owns nothing and defers nothing. A Dragonfly snapshot upgrade does not defer recovery at all: it pauses only the Dragonfly manager.
A recovery or convergence step that was already running when the handoff started finishes before the handoff touches MySQL. Each such step is bounded: a drain pass by 5s, the recovery decision and the replication rewrite by 30s each (the RecoveryInProgress status write between them does not hold the handoff), and a source repoint by 20s plus up to 20s to restart the unchanged channel if it fails. A handoff therefore waits at most about 40s. A planned failover waits for such a step before it is granted its claim, so before anything is fenced: it stays in Admitting with admission.waitReason: RecoveryInFlight, and only if the step outlasts the 2-minute admission deadline does it end NotStarted with AdmissionTimeout. Nothing is fenced either way.
Divergence detected (manual intervention required)
If the old primary has committed transactions that never replicated to the new primary, the operator:
- Keeps the site fenced (
super_read_only=ON) - Records the divergent GTID set and transaction count in
status.sites[].divergentGtidandstatus.sites[].divergentTransactionCount - Sets
status.sites[].recoveryStatetoRecoveryBlocked - Sets the
RecoveryPendingcondition toTruewith reasonDivergentTransactions, andDegradedtoTruewith reasonDivergentTransactions - Emits the
bloodraven_divergent_transactionsPrometheus metric and aDataLossDetectedWarning Event - Excludes the site from ordered-update handoffs and planned failovers, and ranks it last for emergency failover (see Divergent replicas)
While a site is RecoveryBlocked, the operator re-verifies the divergence roughly every 30 seconds rather than freezing the first report. If the site diverges further before you resolve it (for example its pod respawned writable, accepted a few writes, and was re-fenced), divergentGtid and the count refresh to the full current set. A writable observation does not erase that evidence; split-brain remains blocked. When the site is both the recorded failover target and the unique, directly confirmed writable primary, the report becomes the DivergentPromotion condition instead of disappearing. If someone repoints the site's replication by hand, the replica GTID audit takes over re-verifying the report and keeps it until containment is proven; the report keeps divergenceDetectedBy=OldPrimaryRecovery, so it still makes the deployment API refuse leases. If the divergence is resolved externally — you replay the missing transactions onto the new primary so its GTID set comes to contain the old primary's — the re-check notices containment and automatically rejoins the site as a replica.
To recover a divergent site:
- Investigate the divergent transactions to understand what data was lost (check
status.sites[].divergentGtid) - Trigger a reclone with
kubectl bloodraven reclone <name> <site>, which builds the annotation value, or annotate by hand. The value names the group and its uid, becauseCLONE INSTANCEwipes the site's datadir, and includes the first 8+ characters of the source UUID of the observeddivergentGtidas a confirmation token:# Read the divergent GTID and the group's uid first: kubectl get mysqlfailovergroup <name> -o jsonpath='{.status.sites[?(@.name=="<site>")].divergentGtid}' kubectl get mysqlfailovergroup <name> -o jsonpath='{.metadata.uid}' # Then annotate (the prefix is part of the UUID, before its first ':'): kubectl annotate mysqlfailovergroup <name> \ bloodraven.shipstream.io/reclone-site=<site>:confirm=<name>:uid=<uid>:gtidPrefix=<uuid-prefix> - The operator validates the group name, the uid and that the prefix matches the observed
divergentGtid— a mismatch is rejected with aRecloneRejectedWarning Event, so a fat-fingered site name can't destroy the wrong replica. When a site has nodivergentGtid(cold reclone: PVC loss, manual rebuild), usekubectl bloodraven reclone <group> <site> --coldto provide the required destructive confirmation. - The operator runs
CLONE INSTANCEon the target site, replacing all data with a fresh copy from the current primary. ARecloneRequestedEvent marks the start.
See Recovering a divergent old primary for the full procedure.
Prerequisites
Old primary recovery uses the replication credentials in the operator Secret (spec.credentials.operatorSecretName): MYSQL_REPLICATION_USER and MYSQL_REPLICATION_PASSWORD, set together; with neither, the operator's username and password replicate. The first-boot init script creates a dedicated replication user with REPLICATION SLAVE, REPLICATION CLIENT, BACKUP_ADMIN, CLONE_ADMIN when the MySQL datadir is empty. On a datadir that already exists, create it on every site by hand with those grants. The operator does not rotate a dedicated replication user's password: change it in MySQL as well as in the Secret.
Split-brain resolution
When the state machine observes both sites as Writable simultaneously, the operator's response is tiered:
- After a prior operator-initiated failover -- The operator already knows which site it promoted (
status.lastFailover.target). The other site being writable means the old primary returned. The operator fences it immediately (SET GLOBAL super_read_only=ON) and recovery proceeds on the next poll. This runs regardless ofspec.splitBrainPolicy. - No prior failover history,
spec.splitBrainPolicy.sitePrioritiesis non-empty -- The first listed site that is currently writable wins. The operator fences every other writable site and re-promotes the winner through the standard failover path. The anti-flap cooldown still applies to this promotion. - No prior failover history, no priorities configured -- The operator alerts only (
SPLIT BRAIN: both sites are writable) and takes no automated action. This is the default.
When sitePriorities applies
sitePriorities is an ordered tiebreaker for states the operator cannot resolve from its own history. The two common triggers:
- Fresh deploy with existing data, on pods that come up writable. Both sites are writable and
status.lastFailover.targetis empty because this operator instance has never failed anything over. WithoutsitePriorities, the operator alerts and waits for an admin. Everymysqldnow starts with--read-only=ON, so this needs pods from before that flag or a site unfenced by hand; with the flag, the same group comes up all read-only. That isNoPrimary, not split brain: the fresh-deploy bootstrap refuses sites that hold data,sitePrioritiesdoes not apply, and an admin picks the primary. - Operator restart amnesia. The in-memory failover target is repopulated at startup from the newer of
status.lastFailover.targetand the out-of-band annotation (see Where the cooldown is stored), so a failure on either durable path no longer costs the operator its history. But if a split brain occurred during the restart window — for example, an old primary came back while the operator was restarting — the operator may never have had an opportunity to record the most recent failover at all.sitePrioritiesprovides a deterministic answer in this case.
When history is available (case 1 above), the operator trusts it and does not consult sitePriorities. This preserves the invariant that the site most recently promoted keeps its writes.
Configuration
apiVersion: shipstream.io/v1alpha1
kind: MysqlFailoverGroup
metadata:
  name: orders
spec:
  sites:
    - name: iad
      serverID: 101
      # ...
    - name: pdx
      serverID: 102
      # ...
  splitBrainPolicy:
    sitePriorities: [iad, pdx]  # iad wins when writable; pdx is next
Every entry must match a PrimaryCandidate in spec.sites and appear once; the CRD's CEL validation rejects other names, non-promotable sites and duplicates at admission time. An empty or omitted list leaves unresolvable split brain in alert-only mode.
Data-loss implications
sitePriorities is a policy decision, not a safety feature. When the operator fences a losing site to resolve a split brain:- Any transactions committed on the losing site that did not replicate to the winner are isolated.
- Those transactions are not automatically replayed, merged, or preserved. They remain on the losing site's PVC but are outside the replication stream.
- When the fenced site attempts to rejoin, Bloodraven's existing divergent-GTID detection compares
executed_gtid_seton both sides. If the loser has GTIDs the winner never saw, rejoin is blocked and the site must be recloned to recover. The divergent GTID set and transaction count are recorded instatus.sites[].divergentGtidandstatus.sites[].divergentTransactionCount. - In other words,
sitePrioritiesmakes split-brain resolution fast and deterministic by selecting one history branch. The loser's unreplicated writes are isolated and surfaced through theRecoveryBlockedcondition andbloodraven_divergent_transactionsgauge, but they are not merged into the winner.
Configure sitePriorities only when your operational model has a clear authority order -- for example, a primary region that should win whenever it is writable, followed by explicit fallback regions.
Observability
- Metric:
bloodraven_split_brain_auto_resolve_total{prefer_site="<name>"}-- counter, incremented for a successful losing-site fence; the retained label name identifies the winning site. - Log event:
split-brain auto-resolve: fencing non-preferred site per spec.splitBrainPolicy.sitePrioritiesatWARN, withwinnerandfencedSitefields. - The standard failover log, metric (
bloodraven_failovers_total), and DNS-flip metric (bloodraven_dns_flips_total) also fire, since split-brain resolution runs through the same promotion path.
Anti-flap cooldown
To prevent rapid failover oscillation (e.g., a flapping network link), the operator enforces a cooldown period between automatic failovers. The default is 5 minutes, configurable via spec.failoverCooldown.
During the cooldown:
- The operator continues to monitor both sites and update status
- Automatic failovers are suppressed
- Manual intervention can still be performed (see Operations)
The cooldown timer resets after each failover.
Where the cooldown is stored
The last failover time and target are written to two places on every promotion, so an operator restart cannot silently reset the cooldown:
| Location | Written by |
|---|---|
status.lastFailover (time, target, promotionGtidExecuted) | the per-poll CR status update |
bloodraven.shipstream.io/last-failover, bloodraven.shipstream.io/last-failover-target, bloodraven.shipstream.io/promotion-gtid-executed and bloodraven.shipstream.io/promotion-gtid-executed-for annotations | a merge patch issued inline with the promotion, conditioned on the object's resourceVersion |
The two travel different API paths — the status subresource has its own RBAC rule and admission chain — so an outage on one does not take the other with it. Both writes retry every poll until accepted, and a restarting operator rehydrates from whichever copy carries the later timestamp, including the promotion watermark (status.lastFailover.promotionGtidExecuted) that goes with it. Neither copy is ever moved to an older failover time: the annotation patch re-reads and writes only when its record is newer (at an equal time, second precision, only to change the target or to add a missing watermark), and the status write applies the same timestamp rule. A watermark over 64 KiB does not fit in an annotation; only the status copy carries it then (ERROR promotion watermark too large for the out-of-band failover record; only the status copy carries it). The promotion-gtid-executed-for annotation binds the watermark to its event (<RFC3339 last-failover> <last-failover-target>) and is written and deleted together with promotion-gtid-executed. A restart reads the watermark annotation only when that binding names the event the last-failover and last-failover-target annotations record, so a writer that advances only those two keys cannot pair a new event with an older event's watermark. A stored copy whose failover time is more than 5 minutes ahead of the writing operator's clock is no barrier: a restart already ignores such a copy, and the next promotion writes over it instead of keeping it as the newer record.
A restart that had to fall back to the annotations logs restored lastFailover from out-of-band annotations at WARN. That means this group's status writes were failing when it last promoted, and is worth alerting on. Losing the cooldown across a restart requires both paths to be rejecting writes at once; see Known limitations → Operator availability.
The annotations are operator-owned bookkeeping. Editing or removing them by hand changes what a restart believes about the cooldown; the running process keeps its in-memory value either way and rewrites both copies on its next promotion.
Ordered updates
When spec.updateStrategy.type is OrderedUpdate, spec changes (such as a new image, effective per-site MySQL config, or resource adjustments) are rolled out with zero downtime:
This sequence ensures:
- The active primary is never restarted while serving traffic
- Replication is healthy and the rolled pod has been Ready for 30s before each transition
- At most one site is unavailable at any time
- No committed transaction is lost in the handoff
The handoff of the active site is a maintenance handoff, not an emergency failover. The emergency path drains only the relay log the standby has already received, which is the right trade-off when the primary is gone but would silently drop transactions the healthy primary committed and the standby had not yet fetched. The handoff instead proves catch-up against the source:
- The operator reads the standby's
GTID_EXECUTED, then the active site's while it is still writable. A standby holding transactions the active site lacks is refused here (maintenance handoff refused; candidate has transactions the source lacks): promoting it would make that history authoritative, which is how an install already damaged by issue #202 would lose its newer writes. It then waits up to 30s for the standby to contain the active site's set. A standby that cannot catch up is refused here too, before any write is paused; the log showsmaintenance handoff refused; source not fenced. - It fences the active site with
super_read_only=ON(a failed fence refuses the handoff), kills application connections, and readsGTID_EXECUTEDagain. Nothing can be added to that set now. - It waits for the standby's
GTID_EXECUTEDto contain the fenced set, then promotes the standby. Steps 2 and 3 share one 30s budget that starts at the fence, and every probe in them is bounded by it. Writes are refused for that budget plus the promotion itself or, on abort, up to 10s to unfence the active site. Because of step 1 the fenced phase is normally sub-second. - Promotion runs on one pinned connection to the standby:
STOP REPLICA, a re-check thatGTID_EXECUTEDequals the fenced set (nothing missing and nothing the active site lacks),RESET REPLICA ALL, the same re-check on the recorded promotion GTID, then clearing the read-only flags. Extra transactions at either re-check abort the handoff like a missing one: the standby's replication is restarted, the active site is unfenced, and writes are never enabled on the standby. The connection cannot silently reconnect, so the server that passed the proof is the one made writable; if the standby pod is replaced or the connection drops, the next statement fails and the handoff aborts. If the abort comes afterRESET REPLICA ALLmay have run, the operator re-creates the standby's replication channel to the active site and restarts it.
Both waits also probe the active site. If it stops answering for about 10s, the handoff ends at once, so the emergency failover that an ordered update holds off can act on the lost primary instead of waiting out the budget.
If the fenced phase runs out of budget, the standby's applier reports an
error, a GTID set cannot be read or parsed, the standby no longer holds the
fenced set at promotion, or the active site stops answering, the operator
clears both super_read_only and read_only on the active site, leaves the
standby a read-only replica, and ends the update. The active site's drift
stays queued, so the handoff is retried on a later reconcile. Look for
maintenance handoff refused; source not fenced (refused before the fence)
or maintenance handoff aborted; source unfenced (aborted after it) in the
operator log (see the
log schema).
One failure is not an abort: the standby's final read_only=OFF returns an
error after it may have applied. The active site then stays fenced, because
the standby may already accept writes, and the update ends with ordered update failed (the error ends (source left fenced: the candidate may already accept writes)). Before reporting it, the operator reads the
standby's read_only on a pooled connection, up to three times. If the
standby answers writable, the handoff happened: the operator logs ordered update: handoff promotion returned an error but the standby is writable; recording the handoff and records it as a promotion (the lastFailover record with its time,
target and promotionGtidExecuted, the anti-flap cooldown and DNS). If it cannot read the standby, it logs ordered update: could not read the standby's read_only after a failed handoff promotion, records nothing,
and the next topology poll observes the standby. A standby that answers
read-only is not recorded either. In every case the old active site is not
rolled.
After the handoff, the operator updates the old active site and repoints it
at the new primary. Updating it replaces its pod, and mysqld comes back with
read_only only, so the operator first fences it again with
super_read_only=ON (a failed fence refuses the repoint). It then compares
the two GTID_EXECUTED sets once more before CHANGE REPLICATION SOURCE.
The handoff already guarantees that the new primary holds everything the old
active committed. If the old active nonetheless holds transactions the new
primary lacks, or either set cannot be read, the operator does not repoint
it. Replicating from the new primary would leave those transactions as
errant GTIDs on a replica whose threads look healthy. The replica GTID
audit would report it only after the update ends, and
until then it would count as a clean replica. Instead the old active stays
fenced with no replication channel, and the update ends with ordered update failed. Old-primary recovery then picks the site
up. It either rejoins the site as a replica or, if the divergence is real,
reports status.sites[].divergentGtid with
divergenceDetectedBy=OldPrimaryRecovery and blocks so the site can be
recloned. An old active that came back on an empty datadir is the exception:
its set holds only server-init transactions under a new server_uuid, so the
update refuses it the same way, but recovery treats it as empty and leaves it
to auto-clone without reporting a divergentGtid.
For groups with more than two sites, every drifted non-active follower is
updated sequentially and must be read-only with a direct healthy source before
and after restart. If the active site has no drift, the rollout completes
without failover; this is the normal reader-only configuration path. If the
active site is drifted, only a healthy PrimaryCandidate standby may receive
the handoff. A reader or DisasterRecovery follower is never promoted to facilitate an
update, and failed or unprocessed drift remains queued for a later reconcile.
A standby that is mid-keyring-rotation (UnsealReason=Rotation) or still
pending its post-restore reclone is not a handoff target. The operator
re-checks this, together with the divergence report below, when it picks the
standby rather than relying on what it saw when the update was planned, so a
rotation stamped while followers were rolling still stops the handoff. If no
eligible standby remains, the update ends with ordered update failed
naming the reason, before anything is fenced. Conversely, a
bloodraven.shipstream.io/rotate-keyring request is refused while an
ordered update is pending or running; that decision is made against the
operator's live update state, not only status.updatePhase.
A standby with a divergence report (recoveryState=RecoveryBlocked, see
Divergent replicas) is not a handoff target either.
When it is the only candidate, drifted followers are still updated, but the
active site's update stalls without fencing anything: the update fails with
<site> is divergent (N transactions the primary lacks); reclone or reconcile before the active site can be updated, and the operator logs
ordered update: active-site update stalled; standby is divergent every 30s
while Degraded=DivergentTransactions names the set. The stall is
intentional and lasts until the standby is recloned or the primary is made
to contain the set; the update then resumes on its own.
Every rolled site must also have a Ready pod, not only healthy MySQL. The
operator reaches MySQL through each site's -internal Service, which
publishes not-ready addresses. MySQL can therefore answer, and replicate,
while the pod is out of every application Service, for example because the
new pod template's sidecar cannot start, which also leaves the site without
self-fencing. MySQL health alone would let the update hand the active role to
such a site and then roll the old active into the same state.
A rolled site therefore counts as updated only when, within the same 5 minute
budget as the replication wait, its Deployment has rolled out the new template
and that template's pod has been Ready (every container passing its
readiness probe) continuously for 30 seconds. A pod that is Ready at the
moment of a check is not enough: a crash-looping container passes its probe
between crashes. The 30 seconds run from the later of the pod's last
transition to Ready and the start of its newest container run, native
sidecar init containers included, so a container restart starts the count
again even when the pod's Ready condition did not catch it. Every rolled
site therefore takes at least 30 seconds. A replaced pod that is still Ready
while it terminates is never mistaken for the new one.
Both times are recorded by the node and compared with the operator's clock. A node clock ahead of the operator's delays the verdict by the difference; one behind it shortens the 30 seconds by the difference.
Before it takes another site out of service (the next follower, or the active
site's handoff), the operator checks again that every site already running the
new template has a pod Ready for 30 seconds, including the site it just
rolled and a site an earlier attempt rolled that no longer shows drift. A
template that breaks pods stops at the first site it broke, and a standby
whose pod is not Ready is never handed the active role. While the operator
waits for a pod it keeps probing the replication source, so a primary lost
during that wait still ends the update after about 10 seconds.
When the update stops on a pod:
- The
Updatingcondition staysTrue, with reasonOrderedUpdateStalled: the update is still in progress, stopped on that site. The message names the site, the pod and why it is notReady, for examplesidecar not ready: crash looping, last exit code 1 (Error). A container that has restarted is reported in those words in every phase of its crash loop (waiting out its back-off, running again,Readyagain for less than 30 seconds, terminated again), so while the cause stays the same the message does not change from one retry to the next. A pod that has beenReadyfor less than 30 seconds with no recent container restart readspod Ready for less than 30s. A Warning EventOrderedUpdateStalledcarries the same text, once per stall, and the operator logsordered update: stalled; site pod not Ready. - Nothing else is rolled or handed off. The active site keeps serving, and the remaining drift stays queued.
- The update retries every 30s and resumes once the pod has been
Readyfor 30 seconds. If no site is left to roll, the operator checks the stalled pod on the same cadence and clears the condition by the same rule, so a crash-looping pod caught between crashes does not clear it.
Fix whatever keeps the pod from starting (the container logs and kubectl describe pod name it). A spec change that repairs the template makes the
broken site drift again, and the update rolls it like any other site.
Automatic cross-site actions are suppressed while an update runs, because the site being rolled looks unreachable. That suppression never outlasts the primary: if the replication source stops answering while a rolled site is catching up (an updated follower waiting on the active primary, or the old active waiting on the primary it was just handed to), the operator abandons the wait after roughly 10 seconds of consecutive failed probes and ends the update. The suppressed failover or promotion-refusal evaluation then runs on the next poll instead of waiting out the 5 minute catch-up timeout.
Without OrderedUpdate, both sites are updated simultaneously, which may cause brief downtime if both pods restart at the same time.
For MySQL image changes, see the Upgrade and version-skew policy. The replica-first ordering above is the MySQL-required direction for a rolling version upgrade.